Experiment Design and Evaluation of AI Systems
Reliable eval means efficient product cycles, informed decisions, better products, happier customers.
Sessions
If you’d like to follow along as I add new lessons, you’re very welcome to subscribe on YouTube.
Part I: AI Evals as Experiments
-
I.1
The Language of Uncertainty
A gentle introduction to probability, beliefs, and random variables.
-
I.2
Why are evals in AI different?
From traditional software to ML to AI agents — an eval is an experiment, not a check.
Playgrounds: Sampling noise explorer
-
I.3
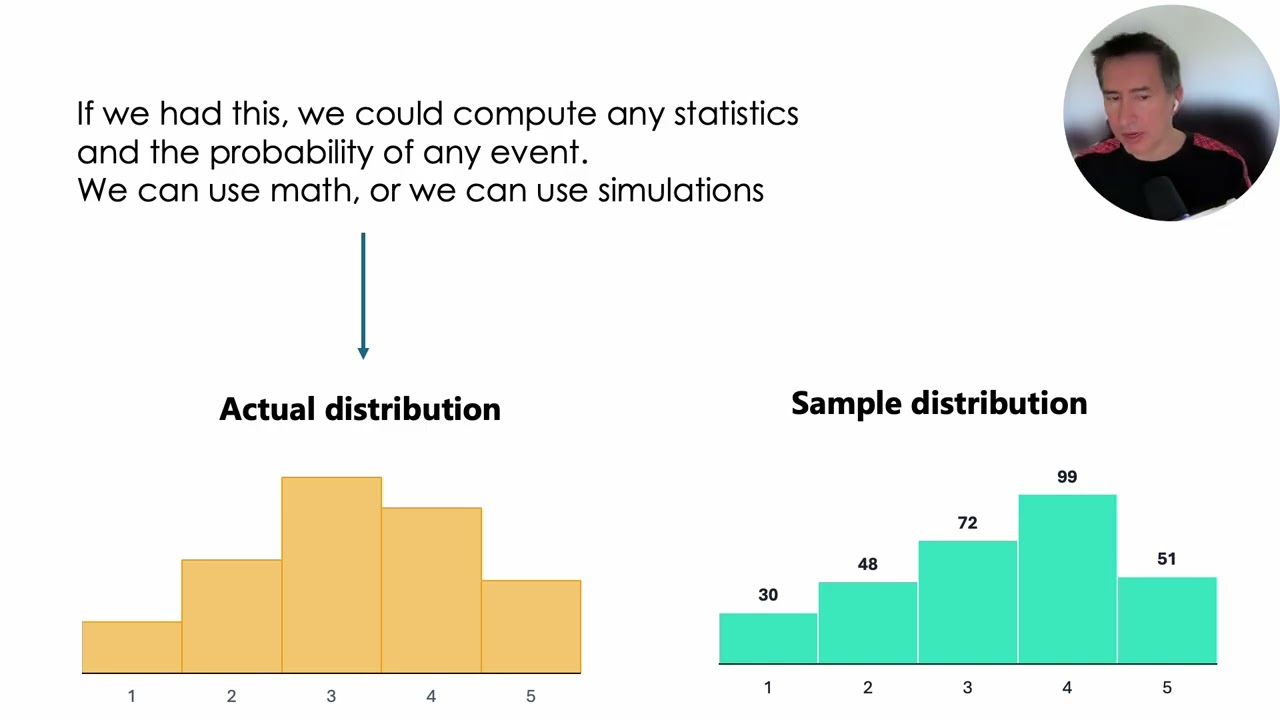
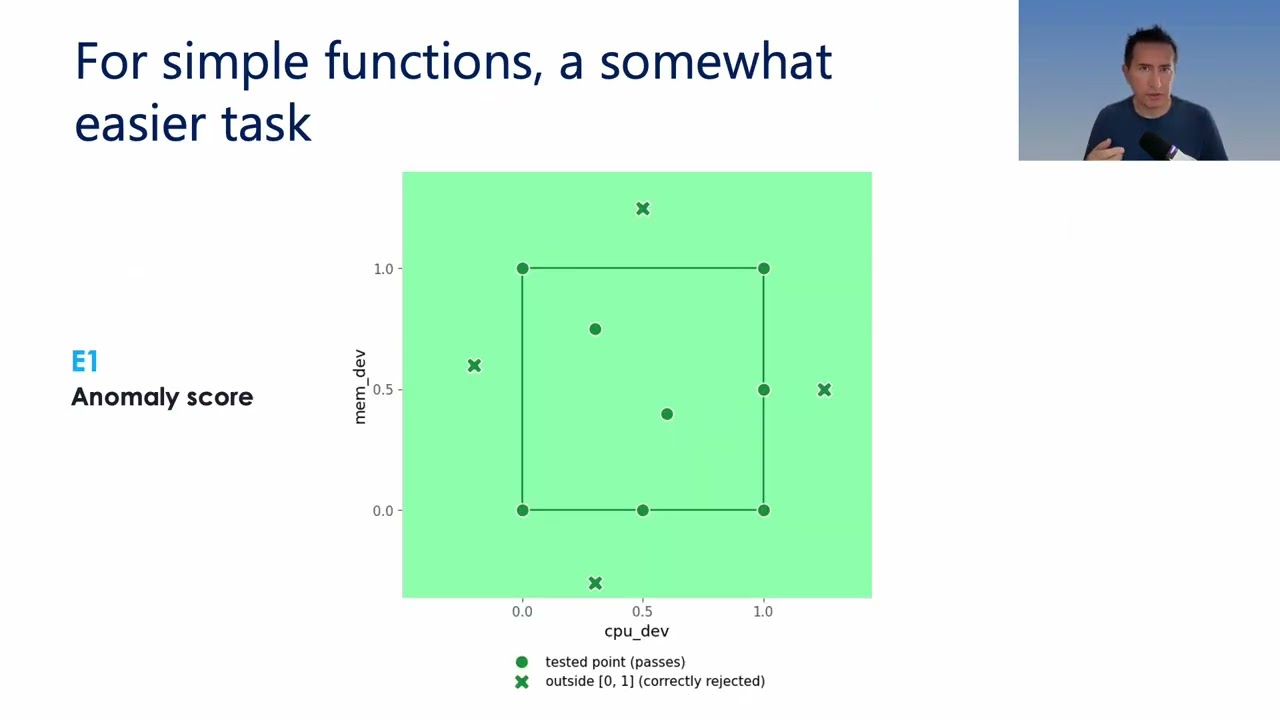
AI Eval means Estimating the Distribution of Random Variables
Playgrounds: Running Examples
-
I.4
Objectives, System under Test, and Metrics




Part II: How, and how much, a poorly designed eval lies to you
Each session presents a problem, why it matters, how to report on it, and how to manage it.
-
U.1
Sample Size
-
U.2
Closed-Book Overfitting
Playgrounds: Story Finder, Inflated Estimates
-
U.3
Open-Book Overfitting
-
U.4
Noisy and Biased Judges
Video releases Saturday, October 24
-
U.5
Dataset Representativeness and Variability
Video releases Saturday, October 31
-
U.6
Other Sources of Brittleness in Eval Results
Video releases Saturday, November 7
-
U.7
How the Problems Compound Rather Than Cancel Out
Releases Saturday, November 14
Playgrounds: How Problems Compound


Part III: Designing Reliable Experiments
From product question to experiment plan, measured result, decision report, and next iteration.
-
D.1
Hill-Climbing
Video coming in November 2026
Hill-Climbing I — Slides (PDF)
Playgrounds: Inflated Estimates, Story Finder, Open-Book Overfitting, Judges & Compounding Lab, Climbing on Noisy Labels, How Problems Compound
-
D.2
Dataset Selection and Sampling
Coming in November 2026
-
D.3
Designing the Evaluation Workflow
Coming in November 2026
-
D.4
Designing Reliable Comparisons
Coming in November 2026
-
D.5
Reporting Evaluation Results
Coming in November 2026
Optional deep dives
Three totally optional take-home reads for the curious — background that explains the "why" behind the language we use, but is not required to follow the course.
-
The Gaussian & the Central Limit Theorem
Where statistics came from, and why the normal distribution keeps showing up — felt, not proven.
Releases after the lesson series
-
Conditional Probability & Bayes
What a probability means once you condition on evidence — and why "92% confident" is a promise the model may not keep.
Releases after the lesson series
-
Understanding and Managing Uncertainty
Every source of uncertainty the course meets, in one place — how each shows up in a number, how to report it honestly, and what actually reduces it.
Releases after the lesson series
Readings
-
Revised estimates of the types and durations of long Covid symptoms based on claims records from 245 Million US patients (preprint PDF)
Even a huge dataset can give a precise but biased answer. Choose comparison groups carefully and use negative controls to detect spurious effects.